
SingleStore Notebooks

Note
This tutorial is meant for Standard & Premium Workspaces. You can't run this with a Free Starter Workspace due to restrictions on Storage. Create a Workspace using +group in the left nav & select Standard for this notebook. Gallery notebooks tagged with "Starter" are suitable to run on a Free Starter Workspace
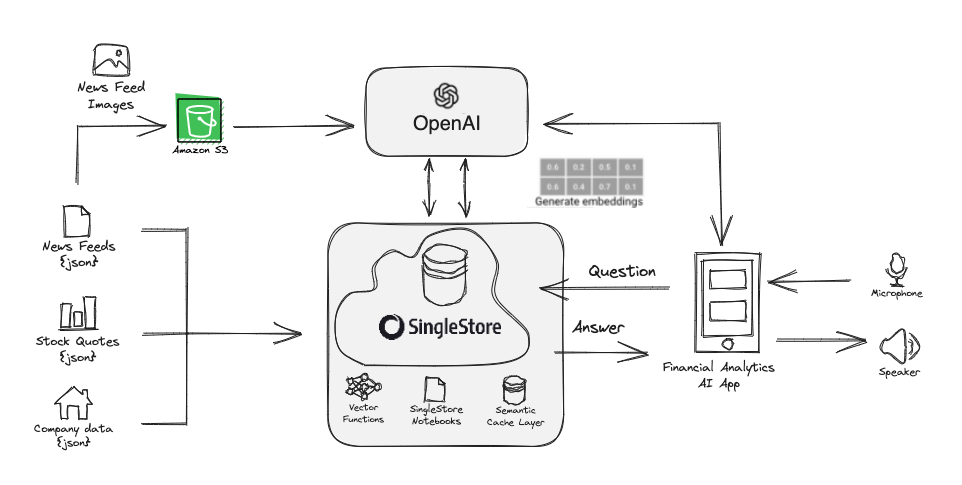
By the end of this notebook you will have a small application that answers questions about stock-market data in plain English, and that can see, hear and speak. Prices, company profiles and news articles are pulled from one free API; a LangChain SQL agent turns your questions into MySQL and answers in prose; each question is cached alongside its embedding, so a later question that means the same thing is answered from the cache; the answer is spoken and transcribed back; and a news photo belonging to one of the stored rows is captioned by a vision model.
All of it lives in one SingleStore database. The rows, the embeddings and the cache sit together, so
the cache lookup is an ordinary SQL query over a VECTOR column — there is no second system to keep in
sync.
Step 1 — one database and four tables, including the VECTOR columns the cache needs
Step 2 — install LangChain, enter your API keys, open a connection
Step 3 — ingest prices, company profiles and news sentiment for three tickers
Step 4 — ask questions in English, then put a semantic cache in front of the agent
Step 5 — speak the answer, play it, transcribe it back
Step 6 — fetch a stored article's photo and caption it
Run the cells in order. Every cell is safe to run again, and step 3 re-fetches nothing it already has. Troubleshooting at the end lists the errors worth knowing about in advance.
You need a Standard or Premium workspace, as the alert above says, with a database selected in the drop-down at the top of this notebook — every SQL cell runs against whatever is chosen there.
You also need two accounts, both free to create: Alpha Vantage for the data and OpenAI for the models, which costs a few cents for a full run. ElevenLabs is optional; leave its prompt blank and step 5 uses OpenAI's text-to-speech instead. The links are in the next step.
Budget about five minutes, some of it spent waiting: the Alpha Vantage free tier allows roughly one request per second, so step 3 paces itself. One thing may need a settings change — step 6 fetches a photo from a news site, and a hosted notebook can only reach hosts the workspace firewall allows. Nothing else depends on that step, which is why it is last.
First a database named llm_webinar. Expect a one-line success message and nothing else.
IF NOT EXISTS here and on the tables below means running these cells twice is harmless — it will not
wipe rows that cost you Alpha Vantage requests. To start over deliberately, the Reset Demo
cell at the end drops the database outright.
In [1]:
1%%sql2CREATE DATABASE IF NOT EXISTS llm_webinar;
Action Required
Make sure to select a database from the drop-down menu at the top of this notebook. It updates the connection_url to connect to that database.
Three tables hold what step 3 ingests: stockTable, one row per ticker per trading day;
companyInfo, one row per company with the profile fields Alpha Vantage calls an overview;
and newsSentiment, news articles with sentiment scores and the URL of each article's banner
photo, which step 6 reads. companyInfo is a REFERENCE table because it is tiny — SingleStore
replicates it to every node, so joins against it never move data across the cluster.
The fourth, embeddings, is the semantic cache: a question, its answer, and an embedding of
each. Those embedding columns are VECTOR(1536, F32), SingleStore's native vector type, sized for
what text-embedding-3-small produces. Using the real type rather than a blob means the dimension
of every value is validated on insert, results print readably, and a vector index can be added
later — which is what NOT NULL is there for.
topic_relevance_score is DECIMAL(10, 6) rather than text because step 6 filters on it: numbers
stored as text sort like words, so '0.09' > '0.9'.
The SHOW TABLES cell that follows is your check: expect exactly these four names. If it comes back
empty, the database drop-down at the top of the notebook is pointing somewhere else.
In [2]:
1%%sql2CREATE TABLE IF NOT EXISTS `stockTable` (3    `ticker` varchar(20) CHARACTER SET utf8 COLLATE utf8_general_ci DEFAULT NULL,4    `created_at` datetime DEFAULT NULL,5    `open` float DEFAULT NULL,6    `high` float DEFAULT NULL,7    `low` float DEFAULT NULL,8    `close` float DEFAULT NULL,9    `volume` int(11) DEFAULT NULL,10    SORT KEY (ticker, created_at desc),11    SHARD KEY (ticker)12);13
14CREATE TABLE IF NOT EXISTS newsSentiment (15    title TEXT CHARACTER SET utf8mb4,16    url TEXT,17    time_published DATETIME,18    authors TEXT,19    summary TEXT CHARACTER SET utf8mb4,20    banner_image TEXT,21    source TEXT,22    category_within_source TEXT,23    source_domain TEXT,24    topic TEXT,25    topic_relevance_score DECIMAL(10, 6),26    overall_sentiment_score REAL,27    overall_sentiment_label TEXT,28    `ticker` varchar(20) CHARACTER SET utf8 COLLATE utf8_general_ci DEFAULT NULL,29    ticker_relevance_score DECIMAL(10, 6),30    ticker_sentiment_score DECIMAL(10, 6),31    ticker_sentiment_label TEXT,32    SORT KEY (`ticker`,`time_published` DESC),33    SHARD KEY `__SHARDKEY` (`ticker`,`time_published` DESC),34    KEY(ticker) USING HASH,35    KEY(authors) USING HASH,36    KEY(source) USING HASH,37    KEY(overall_sentiment_label) USING HASH,38    KEY(ticker_sentiment_label) USING HASH39);40
41CREATE ROWSTORE REFERENCE TABLE IF NOT EXISTS companyInfo (42    ticker VARCHAR(10) PRIMARY KEY,43    AssetType VARCHAR(50),44    Name VARCHAR(100),45    Description TEXT,46    CIK VARCHAR(10),47    Exchange VARCHAR(10),48    Currency VARCHAR(10),49    Country VARCHAR(50),50    Sector VARCHAR(50),51    Industry VARCHAR(250),52    Address VARCHAR(100),53    FiscalYearEnd VARCHAR(20),54    LatestQuarter DATE,55    MarketCapitalization BIGINT,56    EBITDA BIGINT,57    PERatio DECIMAL(10, 2),58    PEGRatio DECIMAL(10, 3),59    BookValue DECIMAL(10, 2),60    DividendPerShare DECIMAL(10, 2),61    DividendYield DECIMAL(10, 4),62    EPS DECIMAL(10, 2),63    RevenuePerShareTTM DECIMAL(10, 2),64    ProfitMargin DECIMAL(10, 4),65    OperatingMarginTTM DECIMAL(10, 4),66    ReturnOnAssetsTTM DECIMAL(10, 4),67    ReturnOnEquityTTM DECIMAL(10, 4),68    RevenueTTM BIGINT,69    GrossProfitTTM BIGINT,70    DilutedEPSTTM DECIMAL(10, 2),71    QuarterlyEarningsGrowthYOY DECIMAL(10, 3),72    QuarterlyRevenueGrowthYOY DECIMAL(10, 3),73    AnalystTargetPrice DECIMAL(10, 2),74    TrailingPE DECIMAL(10, 2),75    ForwardPE DECIMAL(10, 2),76    PriceToSalesRatioTTM DECIMAL(10, 3),77    PriceToBookRatio DECIMAL(10, 2),78    EVToRevenue DECIMAL(10, 3),79    EVToEBITDA DECIMAL(10, 2),80    Beta DECIMAL(10, 3),81    52WeekHigh DECIMAL(10, 2),82    52WeekLow DECIMAL(10, 2),83    50DayMovingAverage DECIMAL(10, 2),84    200DayMovingAverage DECIMAL(10, 2),85    SharesOutstanding BIGINT,86    DividendDate DATE,87    ExDividendDate DATE88);89
90CREATE TABLE IF NOT EXISTS `embeddings` (91    `id` bigint(11) NOT NULL AUTO_INCREMENT,92    `category` varchar(255) CHARACTER SET utf8 COLLATE utf8_general_ci DEFAULT NULL,93    `question` longtext CHARACTER SET utf8 COLLATE utf8_general_ci,94    `question_embedding` VECTOR(1536, F32) NOT NULL,95    `answer` longtext CHARACTER SET utf8 COLLATE utf8_general_ci,96    `answer_embedding` VECTOR(1536, F32) NOT NULL,97    `created_at` datetime DEFAULT NULL,98    UNIQUE KEY `PRIMARY` (`id`) USING HASH,99    SHARD KEY `__SHARDKEY` (`id`),100    KEY `category` (`category`) USING HASH,101    SORT KEY `__UNORDERED` (`created_at` DESC)102);
In [3]:
1%%sql2SHOW TABLES;
The hosted image already ships openai, numpy, pandas, requests and singlestoredb, so the
only install is LangChain. Expect about thirty seconds of quiet output.
Two warnings you can ignore: langchain-community — the only home for the SQL toolkit step 4 uses
— announces on import that it is being sunset, and pip may mention conflicts among packages this
notebook never imports.
In [4]:
1%pip install --quiet "langchain>=1.3,<2" "langchain-community>=0.4.2,<0.5" "langchain-openai>=1.5,<2"
Now the imports: standard library, the two SDKs, and the LangChain pieces step 4 needs. Nothing
here touches the network, so this cell returns instantly. A NameError further down usually means
this cell has not run in the current kernel.
In [5]:
1import getpass2import json3import os4import time5from datetime import datetime, timedelta6
7import numpy as np8import openai9import requests10import singlestoredb as s211from dateutil.relativedelta import relativedelta12
13# LangChain moved these in 1.x: `langchain.sql_database` and14# `langchain.agents.agent_toolkits` no longer exist. These are the current paths.15from langchain_community.utilities import SQLDatabase16from langchain_community.agent_toolkits.sql.toolkit import SQLDatabaseToolkit17from langchain_community.agent_toolkits.sql.base import create_sql_agent18from langchain_openai import ChatOpenAI19
20import langchain21
22print(f'openai {openai.__version__} | langchain {langchain.__version__}')23
24# Report whether this image's brotli is one of the affected ones. This is informational25# only — the OpenAI client cell below sidesteps the decoder either way.26try:27    import brotli28
29    brotli.Decompressor().process(brotli.compress(b'probe'), output_buffer_limit=1 << 20)30    print(f'brotli {brotli.__version__}: accepts output_buffer_limit')31except TypeError:32    print(f'brotli {brotli.__version__}: too old for httpx2 (expected on this image) — '33          f'the OpenAI client below will not request brotli-encoded responses')34except ImportError:35    print('brotli not installed — nothing to work around')
Run the next cell and paste each key at the prompt. getpass keeps them off the screen and out of
the saved notebook, which also means re-entering them after a kernel restart.
| Service | What this notebook uses it for | Cost | | --- | --- | --- | | Alpha Vantage | The only data source: daily prices, company overviews, news sentiment | Free key, no card | | OpenAI | Embeddings, the text-to-SQL agent, transcription, image captioning | Paid, a few cents for a full run | | ElevenLabs | Text to speech — the "speak" in the title. Optional | Free tier is enough |
Press Enter at the ElevenLabs prompt to skip it: step 5 falls back to OpenAI's text-to-speech, so you still get audio and the transcription step still has a file to read.
Know this about the Alpha Vantage free tier before step 3
There are two separate limits: about one request per second, and 25 requests per day. A first full run uses about a dozen. The ingest cells pace themselves, report any refusal out loud rather than skipping rows quietly, and fetch only what is missing — so re-running a loaded notebook makes no requests at all, and a run cut short by the daily quota resumes where it stopped. Set AV_REFRESH = True in the first ingest cell when you want fresh data on purpose.
In [6]:
1alpha_vantage_apikey = getpass.getpass('enter alphavantage apikey here')2openai_apikey = getpass.getpass('enter openai apikey here')3
4# Optional. Press Enter to skip and fall back to OpenAI text-to-speech in step 5.5elevenlabs_apikey = getpass.getpass('enter elevenlabs apikey here (optional, Enter to skip)').strip()6
7assert alpha_vantage_apikey, 'Alpha Vantage key is required — every table below is loaded from it.'8assert openai_apikey, 'OpenAI key is required for embeddings, the SQL agent, and captioning.'9
10os.environ['OPENAI_API_KEY'] = openai_apikey11print(f'ElevenLabs: {"configured" if elevenlabs_apikey else "skipped, using OpenAI TTS"}')
One client, used by everything: embeddings, transcription, speech, captioning, and the LangChain
agent in step 4. It ends with a deliberately cheap embeddings call, so a wrong or unfunded key fails
here rather than a dozen cells later. Expect two printed lines, the second reading
text-embedding-3-small returned 1536 dimensions — the size the embeddings table was declared
for. If you swap in a different embedding model, read the note on the similarity threshold in step 4
first: the threshold is a property of the model, and carrying one over is a silent failure.
The http_client argument turns off brotli compression, which the version on this image cannot
decode. Without it you get APIConnectionError: Connection error printed under a successful
HTTP/1.1 200 OK — an error that looks like the network or your key and is neither.
In [7]:
1import httpx22from openai import OpenAI3
4# Do not advertise brotli, so the image's brotli 1.1.0 is never asked to decode a response.5http_client = httpx2.Client(headers={'Accept-Encoding': 'gzip, deflate'})6
7client = OpenAI(api_key=openai_apikey, http_client=http_client)8
9print(f"Accept-Encoding: {client._client.headers.get('accept-encoding')}")10
11EMBEDDING_MODEL = 'text-embedding-3-small'   # 1536 dimensions, matches the DDL above12CHAT_MODEL = 'gpt-4o-mini'                   # used for the SQL agent and image captioning13
14
15def get_embeddings(inputs: list[str], model: str = EMBEDDING_MODEL) -> list[list[float]]:16    """Return one embedding per input string."""17    return [x.embedding for x in client.embeddings.create(input=inputs, model=model).data]18
19
20# Fail here, on one cheap call, rather than midway through the ingest loops.21_probe = get_embeddings(['connectivity probe'])[0]22print(f'{EMBEDDING_MODEL} returned {len(_probe)} dimensions')23
24assert len(_probe) == 1536, (25    f'{EMBEDDING_MODEL} returned {len(_probe)} dimensions but the embeddings table declares '26    f'VECTOR(1536, F32). Change the DDL to match, or pick a 1536-dimension model.'27)
Expect one line: connected to llm_webinar; all four tables present. If it reports a missing table
or no database selected, the drop-down at the top of the notebook is pointing somewhere other than
where step 1 created things.
The password in a notebook connection URL is a token that expires after about an hour, so the helpers read the URL when they need it and let the driver refresh it. One connection then survives both a token refresh and a change to the database drop-down.
In [8]:
1def current_connection_url() -> str:2    """Return the connection URL as it is now, not as it was at kernel startup.3
4    The password is a JWT that expires after roughly an hour, so a copy taken earlier in the5    session may already be dead. The first two sources are read live.6    """7    url = None8
9    try:10        from singlestoredb.notebook import portal11        url = portal.connection_url12    except Exception:13        pass   # not running inside a SingleStore hosted notebook14
15    url = url or os.environ.get('SINGLESTOREDB_URL') or connection_url16
17    # SINGLESTOREDB_URL carries no scheme, and SQLAlchemy needs one to choose a dialect.18    return url if '://' in url else f'singlestoredb://{url}'19
20
21EXPECTED_TABLES = {'stockTable', 'newsSentiment', 'companyInfo', 'embeddings'}22
23
24def s2_connect():25    """Open a connection that re-reads its credentials rather than pinning them."""26    # track_env=True discards any URL passed to connect() and reads SINGLESTOREDB_URL on every27    # statement, so only ask for it when that variable is actually set.28    if os.environ.get('SINGLESTOREDB_URL'):29        conn = s2.connect(track_env=True)30    else:31        conn = s2.connect(current_connection_url())32
33    try:34        with conn.cursor() as cur:35            # track_env defers connecting, so this statement is what opens the socket.36            cur.execute('SELECT DATABASE()')37            database = cur.fetchone()[0]38
39            cur.execute(40                'SELECT table_name FROM information_schema.tables '41                'WHERE table_schema = DATABASE()'42            )43            tables = {row[0] for row in cur.fetchall()}44
45    except s2.Error as exc:46        if exc.errno == 2628 or 'JWT' in str(exc):47            raise RuntimeError(48                'SingleStore rejected the notebook credentials: the JWT in the connection URL '49                'has expired. It is issued when the kernel starts and lasts about an hour, so a '50                'long session runs past it. Restart the kernel and run the cells again — the '51                'portal issues a fresh token at startup.'52            ) from exc53        raise54
55    assert database, (56        'no database is selected. Pick llm_webinar from the drop-down at the top of the '57        'notebook, then re-run this cell.'58    )59
60    missing = EXPECTED_TABLES - tables61
62    assert not missing, (63        f'connected to {database}, which is missing {sorted(missing)}. Either the DDL cells have '64        f'not been run, or the drop-down points at a different database.'65    )66
67    print(f'connected to {database}; all four tables present')68
69    return conn70
71
72s2_conn = s2_connect()
Everything in the four tables comes from Alpha Vantage. This cell defines one helper the three ingest
cells share, and it exists because Alpha Vantage does not refuse with an HTTP error. A refusal is
HTTP 200 carrying a JSON body with a Note or Information key where the data should be. Code that
trusts the status code cannot tell a refusal from a month with no news: the loop moves on, the tables
come out half full, and the first visible symptom is the agent in step 4 answering confidently about
nothing.
There are two limits on a free key, and telling them apart decides whether retrying is worth anything:
| Limit | What the message says | What helps | | --- | --- | --- | | about 1 request per second | "spreading out your free API requests more sparingly" | pausing between requests | | 25 requests per day | "our standard API rate limit is 25 requests per day" | waiting for the reset, or a premium key |
The per-second limit is the one these loops trip, so alpha_vantage_get() paces itself and retries a
burst refusal with backoff — that pacing is most of step 3's running time.
Because 25 requests a day is few, each cell below asks the database what it already holds and fetches
only the remainder. Re-running a loaded notebook prints no requests made, and hitting the quota
mid-loop is a pause rather than a crash: rows already inserted stay, and re-running tomorrow fetches
what is outstanding. A genuine error, such as a bad key, still stops the cell, and AV_REFRESH = True
in the next cell wipes and reloads.
In [9]:
1# The free tier limits both the day (25 requests) and the burst (about 1 per second). The2# burst limit is the one the loops below trip, because they make their requests back to back.3AV_MIN_INTERVAL = 1.5    # seconds to leave between requests4AV_MAX_ATTEMPTS = 4      # 1 initial try plus 3 retries, for burst refusals only5AV_DAILY_LIMIT = 25      # free-tier requests per key per day, for reporting only6
7# The ingest cells below only fetch what is missing from each table, so re-running the notebook8# costs no Alpha Vantage requests once a table is complete. That matters because the daily quota9# is small enough that a couple of full runs exhausts it, and everything after step 4 then has10# nothing to work with. Set this to True when you actually want fresh data.11AV_REFRESH = False12
13_av_last_call = 0.014_av_requests = 0         # this kernel only; the real quota is per key per day, so a restart15                         # resets this counter without resetting the quota16
17
18def av_redact(text: str) -> str:19    """Blank the key out of a message. Alpha Vantage echoes it back, and output gets saved."""20    return text.replace(alpha_vantage_apikey, '<your key>') if alpha_vantage_apikey else text21
22
23class AlphaVantageRefused(RuntimeError):24    """One of Alpha Vantage's HTTP-200 refusals, tagged with which of the four kinds it is.25
26    A RuntimeError subclass so it still reads as one, but `.kind` lets the ingest cells treat27    an exhausted quota as "stop here and keep what you have" rather than a crash.28    """29
30    def __init__(self, kind: str, hint: str, key: str, message: str, params: dict):31        self.kind, self.hint, self.message = kind, hint, message32        subject = params.get('symbol') or params.get('tickers') or ''33        super().__init__(34            f'Alpha Vantage returned "{key}" instead of data for '35            f'{params.get("function")} {subject} [{kind}]:\n  {message}\n{hint}'36        )37
38
39def av_classify(message: str) -> tuple[str, str]:40    """Work out which of Alpha Vantage's HTTP-200 refusals a message is, and advise.41
42    The order of these tests is the whole point. Every refusal advertises the premium plans,43    and the burst message mentions "premium endpoints", "25 requests per day" and "rate limit"44    all at once — so matching the bare word "premium", or checking the daily quota first, gets45    a throttle diagnosed as a paywall.46    """47    m = message.lower()48
49    # Only the paywall says this, in the singular. "premium endpoints" plural is upsell text.50    if 'this is a premium endpoint' in m:51        return 'paywall', (52            'That endpoint is not on the free tier. This is a paywall rather than a quota, so '53            'waiting for a reset will not help: you need a premium key, or a free endpoint that '54            'returns similar data.'55        )56
57    if 'per second' in m or 'sparingly' in m:58        return 'burst', (59            f'That is the per-second burst limit rather than the daily quota. Requests are '60            f'already spaced {AV_MIN_INTERVAL}s apart and retried with backoff, so seeing this '61            f'means the pacing is still too fast — raise AV_MIN_INTERVAL and re-run.'62        )63
64    if 'per day' in m or 'rate limit' in m:65        return 'quota', (66            f'That is the daily quota ({AV_DAILY_LIMIT} requests at the time of writing), which '67            f'resets on its own; a premium key lifts it. The ingest cells only fetch what is '68            f'missing from each table, so re-running them after the reset will pick up where '69            f'this left off rather than starting over — and the sections after the ingest work '70            f'on whatever is already loaded, so there is no need to wait to keep going.'71        )72
73    if 'invalid api call' in m or 'apikey' in m:74        return 'request', (75            'Alpha Vantage rejected the request itself rather than limiting it — usually a bad '76            'key or a mistyped parameter.'77        )78
79    return 'unknown', 'This refusal is not one of the four we recognise; the message is above.'80
81
82def alpha_vantage_get(**params) -> dict:83    """Call Alpha Vantage, pacing the requests and surfacing its HTTP-200 refusals.84
85    Throttling, invalid keys and premium-only endpoints all come back as HTTP 200 with an86    explanatory key instead of data, so the status code tells you nothing. Burst refusals are87    retried with backoff; a paywall or an exhausted daily quota is raised immediately, since88    retrying those just spends more of the quota.89    """90    global _av_last_call, _av_requests91
92    params['apikey'] = alpha_vantage_apikey93
94    for attempt in range(1, AV_MAX_ATTEMPTS + 1):95        # Space requests out rather than waiting to be told off for bursting.96        wait = AV_MIN_INTERVAL - (time.monotonic() - _av_last_call)97
98        if wait > 0:99            time.sleep(wait)100
101        response = requests.get('https://www.alphavantage.co/query', params=params, timeout=30)102        _av_last_call = time.monotonic()103        # Counted before the refusal check on purpose: a throttled or refused call is still a104        # request Alpha Vantage served, so assume it counts against the daily quota too.105        _av_requests += 1106        response.raise_for_status()107
108        payload = response.json()109
110        refusal = next(111            (112                (key, str(payload[key]))113                for key in ('Note', 'Information', 'Error Message')114                if key in payload115            ),116            None,117        )118
119        if refusal is None:120            return payload121
122        key, message = refusal123        message = av_redact(message)124        kind, hint = av_classify(message)125
126        if kind == 'burst' and attempt < AV_MAX_ATTEMPTS:127            backoff = AV_MIN_INTERVAL * 2 ** attempt128            print(f'    burst limit hit, waiting {backoff:.0f}s then retrying '129                  f'(attempt {attempt} of {AV_MAX_ATTEMPTS - 1})')130            time.sleep(backoff)131            continue132
133        raise AlphaVantageRefused(kind, hint, key, message, params)134
135
136def av_report() -> None:137    """Say how many requests this kernel has spent, since the quota is easy to walk into."""138    print(f'  ({_av_requests} Alpha Vantage request(s) this kernel, of about '139          f'{AV_DAILY_LIMIT} per key per day)')140
141
142def already_loaded(query: str) -> set:143    """Return what a table already holds, as a set of values or of tuples.144
145    This is what makes the ingest resumable. Each cell below asks the database what it already146    has and fetches only the rest, so a run that stopped on the daily quota picks up where it147    left off tomorrow instead of starting over — and a run with nothing missing spends nothing.148    """149    with s2_conn.cursor() as cur:150        cur.execute(query)151        rows = cur.fetchall()152
153    return {row[0] if len(row) == 1 else tuple(row) for row in rows}154
155
156def av_stopped_early(exc: 'AlphaVantageRefused', remaining: int) -> None:157    """Explain a quota stop as the pause it is, rather than as a failure."""158    print(f'\n  stopped early on the {exc.kind} limit, with {remaining} item(s) still to fetch.')159    print(f'  {exc.message}')160    print('  What is already loaded above is kept. Re-run this cell once the quota resets and '161          'it will fetch only what is missing.')162
163
164def get_past_months(num_months: int) -> list[str]:165    """Return the current month and the preceding ones, as YYYY-MM strings."""166    today = datetime.today()167    return [168        (today - relativedelta(months=n)).strftime('%Y-%m')169        for n in range(num_months)170    ]171
172
173ticker_list = ['TSLA', 'AMZN', 'PLTR']174
175num_months = 2176year_month_list = get_past_months(num_months)177
178requests_needed = len(ticker_list) * (2 + num_months)179
180print(f'tickers: {ticker_list}')181print(f'months:  {year_month_list}')182print(f'a first full run makes about {requests_needed} Alpha Vantage requests, against a '183      f'free-tier limit of {AV_DAILY_LIMIT} per key per day,')184print(f'and takes at least {requests_needed * AV_MIN_INTERVAL:.0f}s once paced '185      f'{AV_MIN_INTERVAL}s apart.')186print(f'AV_REFRESH is {AV_REFRESH}, so the cells below will '187      + ('refetch every ticker and month.'188         if AV_REFRESH else 'fetch only what is missing from the tables.'))
One request per ticker — TSLA, AMZN and PLTR by default — so about five seconds with the pacing. Expect a line per ticker saying how many daily bars were inserted, then a row count from the SQL cell that follows: around 300 on a first run, 100 trading days for each of the three.
This uses TIME_SERIES_DAILY because TIME_SERIES_INTRADAY is premium: a free key gets HTTP 200
carrying "Information": "... This is a premium endpoint ..." and no data. The daily endpoint returns
the latest 100 trading days per request and names the bar fields identically. If your key is
premium, set USE_INTRADAY_PREMIUM = True for 5-minute bars.
In [10]:
1# TIME_SERIES_INTRADAY is a premium endpoint, so the free TIME_SERIES_DAILY is the default.2# Set this to True only if your Alpha Vantage key is on a premium plan.3USE_INTRADAY_PREMIUM = False4
5INSERT_STOCK = """6    INSERT INTO stockTable (created_at, ticker, open, high, low, close, volume)7    VALUES (%(created_at)s, %(ticker)s, %(open)s, %(high)s, %(low)s, %(close)s, %(volume)s)8"""9
10
11def parse_bars(payload: dict, series_key: str, ticker: str) -> list[dict]:12    """Turn one Alpha Vantage time series into rows for stockTable.13
14    Both endpoints name their bar fields identically, so this handles either one.15    """16    series = payload.get(series_key)17
18    if not series:19        raise RuntimeError(20            f'{ticker}: the response has no "{series_key}". Keys present: {list(payload)[:6]}'21        )22
23    rows = []24
25    for timestamp, bar in series.items():26        # Daily timestamps are dates, so pin them to midnight — created_at is a DATETIME.27        created_at = f'{timestamp} 00:00:00' if len(timestamp) == 10 else timestamp28
29        rows.append({30            'created_at': created_at,31            'ticker': ticker,32            'open': float(bar['1. open']),33            'high': float(bar['2. high']),34            'low': float(bar['3. low']),35            'close': float(bar['4. close']),36            'volume': int(bar['5. volume']),37        })38
39    return rows40
41
42def fetch_bars(ticker: str) -> tuple[list[dict], str]:43    """Fetch one ticker's bars, from whichever endpoint the flag above selects."""44    if USE_INTRADAY_PREMIUM:45        rows = []46
47        for year_month in year_month_list:48            payload = alpha_vantage_get(49                function='TIME_SERIES_INTRADAY',50                symbol=ticker,51                interval='5min',52                month=year_month,53                outputsize='full',54            )55            rows += parse_bars(payload, 'Time Series (5min)', ticker)56
57        return rows, '5-minute'58
59    payload = alpha_vantage_get(60        function='TIME_SERIES_DAILY',61        symbol=ticker,62        outputsize='compact',   # 'full' is premium63    )64
65    return parse_bars(payload, 'Time Series (Daily)', ticker), 'daily'66
67
68# Only fetch tickers the table does not already have. A re-run therefore costs no requests once69# every ticker is in, and a run cut short by the daily quota resumes instead of restarting.70# AV_REFRESH = True clears the table first, so everything is fetched again.71if AV_REFRESH:72    with s2_conn.cursor() as cur:73        cur.execute('DELETE FROM stockTable')74
75have = already_loaded('SELECT DISTINCT ticker FROM stockTable')76todo = [t for t in ticker_list if t not in have]77
78for ticker in ticker_list:79    if ticker in have:80        print(f'  {ticker}: already in stockTable, not refetched')81
82for position, ticker in enumerate(todo):83    try:84        rows, kind = fetch_bars(ticker)85    except AlphaVantageRefused as exc:86        # A spent quota, or a burst limit that outlasted its retries, is a pause rather than a87        # failure: keep the tickers already inserted and stop. Anything else is a real error.88        if exc.kind not in ('quota', 'burst'):89            raise90
91        av_stopped_early(exc, len(todo) - position)92        break93
94    with s2_conn.cursor() as cur:95        cur.executemany(INSERT_STOCK, rows)96
97    # Alpha Vantage returns newest first, so the last row is the oldest.98    print(f'  {ticker}: inserted {len(rows)} {kind} bars '99          f'({rows[-1]["created_at"][:10]} to {rows[0]["created_at"][:10]})')100
101if not todo:102    print('stockTable already has every ticker — no requests made')103
104av_report()
In [11]:
1%%sql2SELECT count(*) AS rows_in_stockTable FROM stockTable
One request per ticker again, so another five seconds. Expect one line per company, then a three-row table: ticker, name, sector, market cap, P/E.
The OVERVIEW endpoint returns a flat JSON object in which every value is a string, with missing
values written variously as None, -, or empty. The coerce() helper turns those into real integers,
decimals and dates, and a missing value into NULL rather than 0.0 — a 0.0 P/E is a plausible
number, so the agent would average it into an answer as fact.
In [12]:
1# Alpha Vantage writes missing values as any of these.2MISSING = {'none', '-', '', 'nan'}3
4INT_FIELDS = [5    'MarketCapitalization', 'EBITDA', 'RevenueTTM', 'GrossProfitTTM', 'SharesOutstanding',6]7FLOAT_FIELDS = [8    'PERatio', 'PEGRatio', 'BookValue', 'DividendPerShare', 'DividendYield', 'EPS',9    'RevenuePerShareTTM', 'ProfitMargin', 'OperatingMarginTTM', 'ReturnOnAssetsTTM',10    'ReturnOnEquityTTM', 'DilutedEPSTTM', 'QuarterlyEarningsGrowthYOY',11    'QuarterlyRevenueGrowthYOY', 'AnalystTargetPrice', 'TrailingPE', 'ForwardPE',12    'PriceToSalesRatioTTM', 'PriceToBookRatio', 'EVToRevenue', 'EVToEBITDA', 'Beta',13    '52WeekHigh', '52WeekLow', '50DayMovingAverage', '200DayMovingAverage',14]15DATE_FIELDS = ['LatestQuarter', 'DividendDate', 'ExDividendDate']16STR_FIELDS = [17    'AssetType', 'Name', 'Description', 'CIK', 'Exchange', 'Currency', 'Country',18    'Sector', 'Industry', 'Address', 'FiscalYearEnd',19]20
21COMPANY_COLUMNS = ['ticker'] + STR_FIELDS + DATE_FIELDS + INT_FIELDS + FLOAT_FIELDS22
23
24def coerce(raw, kind):25    """Convert one Alpha Vantage string to a typed value, or None if it is missing.26
27    Returning None rather than 0.0 matters: a zero P/E ratio reads as a real measurement,28    and anything querying this table later cannot tell it apart from one.29    """30    if raw is None or str(raw).strip().lower() in MISSING:31        return None32    try:33        if kind is int:34            return int(float(raw))35        if kind is float:36            return float(raw)37    except ValueError:38        return None39    return str(raw)40
41
42INSERT_COMPANY = (43    'INSERT INTO companyInfo (' + ', '.join(f'`{c}`' for c in COMPANY_COLUMNS) + ') VALUES ('44    + ', '.join(f'%({c})s' for c in COMPANY_COLUMNS) + ')'45)46
47# companyInfo keys on ticker, so a second insert for the same ticker would fail outright.48# Skipping the tickers already present handles that and saves the requests at the same time.49if AV_REFRESH:50    with s2_conn.cursor() as cur:51        cur.execute('DELETE FROM companyInfo')52
53have = already_loaded('SELECT DISTINCT ticker FROM companyInfo')54todo = [t for t in ticker_list if t not in have]55
56for ticker in ticker_list:57    if ticker in have:58        print(f'  {ticker}: already in companyInfo, not refetched')59
60for position, ticker in enumerate(todo):61    try:62        data = alpha_vantage_get(function='OVERVIEW', symbol=ticker)63    except AlphaVantageRefused as exc:64        if exc.kind not in ('quota', 'burst'):65            raise66
67        av_stopped_early(exc, len(todo) - position)68        break69
70    if 'Symbol' not in data:71        raise RuntimeError(f'OVERVIEW for {ticker} returned no Symbol field: {list(data)[:8]}')72
73    params = {'ticker': data['Symbol']}74    params.update({f: coerce(data.get(f), str) for f in STR_FIELDS})75    params.update({f: coerce(data.get(f), str) for f in DATE_FIELDS})76    params.update({f: coerce(data.get(f), int) for f in INT_FIELDS})77    params.update({f: coerce(data.get(f), float) for f in FLOAT_FIELDS})78
79    with s2_conn.cursor() as cur:80        cur.execute(INSERT_COMPANY, params)81
82    missing = sorted(k for k, v in params.items() if v is None)83    print(f'  {ticker}: {data.get("Name")} — {len(missing)} field(s) null'84          + (f' ({", ".join(missing[:4])}...)' if missing else ''))85
86if not todo:87    print('companyInfo already has every ticker — no requests made')88
89av_report()
In [13]:
1%%sql2SELECT ticker, Name, Sector, MarketCapitalization, PERatio FROM companyInfo
The biggest of the three: one request per ticker per month, so six with the default two-month window,
and about ten seconds of pacing. Expect a line per ticker-month with the number of articles inserted,
a note of any skipped, and then a total row count — several hundred rows is normal, since one request
returns many articles. Lines reading already stored, not refetched on a second run are the
resumability described above doing its job.
NEWS_SENTIMENT returns each article with an overall sentiment score and a per-ticker score, plus
a topics list and a banner photo URL. Step 4 queries the scores; step 6 fetches the photo. Articles
with no topics, or no sentiment entry for the ticker being fetched, are skipped and counted rather
than guessed at.
If the cell stops early saying the daily quota is spent, what it inserted is kept and re-running tomorrow picks up the rest. You can continue through step 4 with a partial table.
In [14]:
1INSERT_NEWS = """2    INSERT INTO newsSentiment (3        title, url, time_published, authors, summary, banner_image, source,4        category_within_source, source_domain, topic, topic_relevance_score,5        overall_sentiment_score, overall_sentiment_label, ticker,6        ticker_relevance_score, ticker_sentiment_score, ticker_sentiment_label7    ) VALUES (8        %(title)s, %(url)s, %(time_published)s, %(authors)s, %(summary)s, %(banner_image)s,9        %(source)s, %(category_within_source)s, %(source_domain)s, %(topic)s,10        %(topic_relevance_score)s, %(overall_sentiment_score)s, %(overall_sentiment_label)s,11        %(ticker)s, %(ticker_relevance_score)s, %(ticker_sentiment_score)s,12        %(ticker_sentiment_label)s13    )14"""15
16if AV_REFRESH:17    with s2_conn.cursor() as cur:18        cur.execute('DELETE FROM newsSentiment')19
20# This cell makes one request per ticker per month, so it resumes at that granularity rather21# than per table: ask which (ticker, month) pairs are already stored and fetch only the rest.22# YEAR() and MONTH() rather than DATE_FORMAT because a '%Y-%m' format string in a query would23# collide with the driver's own %(name)s parameter substitution.24have = {25    (ticker, f'{year:04d}-{month:02d}')26    for ticker, year, month in already_loaded(27        'SELECT DISTINCT ticker, YEAR(time_published), MONTH(time_published) '28        'FROM newsSentiment'29    )30}31
32todo = [(t, m) for t in ticker_list for m in year_month_list if (t, m) not in have]33
34for pair in ((t, m) for t in ticker_list for m in year_month_list):35    if pair in have:36        print(f'  {pair[0]} {pair[1]}: already stored, not refetched')37
38for position, (ticker, year_month) in enumerate(todo):39    # One calendar month, from its first day to the first day of the next month.40    month_start = datetime.strptime(year_month, '%Y-%m')41    month_end = month_start + relativedelta(months=1)42
43    try:44        data = alpha_vantage_get(45            function='NEWS_SENTIMENT',46            tickers=ticker,47            time_from=month_start.strftime('%Y%m%dT0000'),48            time_to=month_end.strftime('%Y%m%dT0000'),49            limit=1000,50        )51    except AlphaVantageRefused as exc:52        if exc.kind not in ('quota', 'burst'):53            raise54
55        av_stopped_early(exc, len(todo) - position)56        break57
58    feed = data.get('feed', [])59    rows, skipped = [], 060
61    for item in feed:62        topics = item.get('topics') or []63        ticker_sentiment = item.get('ticker_sentiment') or []64
65        if not topics or not ticker_sentiment:66            skipped += 167            continue68
69        # Use this ticker's own sentiment entry, not the first one in the list. An article about70        # several companies lists all of them, so the original code could store AMZN's relevance71        # score on a row fetched for TSLA — and that would also make the (ticker, month) check72        # above unreliable, since the stored ticker would not be the one we searched for.73        sentiment = next(74            (ts for ts in ticker_sentiment if str(ts.get('ticker')) == ticker), None75        )76
77        if sentiment is None:78            skipped += 179            continue80
81        authors = item.get('authors') or []82
83        rows.append({84            'title': str(item['title']),85            'url': str(item['url']),86            'time_published': datetime.strptime(87                str(item['time_published']), '%Y%m%dT%H%M%S'88            ).strftime('%Y-%m-%d %H:%M:%S'),89            'authors': str(authors[0]) if authors else 'No authors available',90            'summary': str(item.get('summary', '')),91            'banner_image': str(item.get('banner_image') or ''),92            'source': str(item.get('source', '')),93            'category_within_source': str(item.get('category_within_source', '')),94            'source_domain': str(item.get('source_domain', '')),95            'topic': str(topics[0]['topic']),96            'topic_relevance_score': float(topics[0]['relevance_score']),97            'overall_sentiment_score': float(item['overall_sentiment_score']),98            'overall_sentiment_label': str(item['overall_sentiment_label']),99            'ticker': str(sentiment['ticker']),100            'ticker_relevance_score': float(sentiment['relevance_score']),101            'ticker_sentiment_score': float(sentiment['ticker_sentiment_score']),102            'ticker_sentiment_label': str(sentiment['ticker_sentiment_label']),103        })104
105    if rows:106        with s2_conn.cursor() as cur:107            cur.executemany(INSERT_NEWS, rows)108
109    print(f'  {ticker} {year_month}: inserted {len(rows)} articles'110          + (f', skipped {skipped} without topics or this ticker\'s sentiment' if skipped else ''))111
112    # A month with no articles stores no rows, so it looks unfetched next time and costs one113    # request again. Rare for these tickers, and cheaper than a table to track attempts in.114
115if not todo:116    print('newsSentiment already has every ticker and month — no requests made')117
118av_report()
In [15]:
1%%sql2SELECT count(*) AS rows_in_newsSentiment FROM newsSentiment
This is where the notebook stops being a data pipeline. SQLDatabaseToolkit gives the model four tools
— list the tables, read a schema, check a query, run a query — and create_sql_agent wires them into a
loop: the model writes MySQL, runs it against SingleStore, reads the rows back, and answers in prose.
Expect a short confirmation and a deprecation warning from langchain-community; the agent runs in the
cells further down.
A quirk you may hit. Reading a VECTOR column through SQLAlchemy raises AttributeError: 'VECTOR' object has no attribute '_str_impl' on some builds of the SingleStore dialect, and SQLDatabase reads
sample rows from every table. The cell patches that and describes the embeddings table by hand, which
also keeps two 1536-dimension vectors out of the prompt.
In [16]:
1SQL_AGENT_PREFIX = """You are an agent designed to interact with a SQL database called SingleStore.2This sometimes has Shard and Sort keys in the table schemas, which you can ignore.3
4Given an input question, create a syntactically correct {dialect} query to run, then look at the5results of the query and return the answer.6
7If you are asked about similarity questions, you should use the DOT_PRODUCT function.8
9Here are a few examples of how to use the DOT_PRODUCT function:10
11Example 1:12Q: how similar are the questions and answers?13A: select question, answer, dot_product(question_embedding, answer_embedding) as similarity from embeddings;14
15Example 2:16Q: What are the most similar questions in the embeddings table, not including itself?17A: SELECT q1.question as question1, q2.question as question2,18          DOT_PRODUCT(q1.question_embedding, q2.question_embedding) :> float as score19   FROM embeddings q1, embeddings q220   WHERE q1.question != q2.question21   ORDER BY score DESC LIMIT 5;22
23Example 3:24Q: In the embeddings table, which rows are from the chatbot?25A: SELECT category, question, answer FROM embeddings WHERE category = 'chatbot';26
27If you are asked to describe the database, you should run the query SHOW TABLES.28
29Unless the user specifies a specific number of examples they wish to obtain, always limit your30query to at most {top_k} results. You can order the results by a relevant column to return the31most interesting examples in the database.32
33Never SELECT the question_embedding or answer_embedding columns, and never SELECT * from the34embeddings table: those columns hold 1536-dimension vectors. Compare them with35DOT_PRODUCT(a, b), which returns a single float, and select that instead. Never query for all36the columns from any table, only the columns relevant to the question.37
38You have access to tools for interacting with the database. Only use the below tools, and only39use the information returned by them to construct your final answer. You MUST double check your40query before executing it. If you get an error while executing a query, rewrite the query and41try again up to 3 times.42
43DO NOT make any DML statements (INSERT, UPDATE, DELETE, DROP etc.) to the database.44
45If the question does not seem related to the database, just return "I don't know" as the answer.46"""47
48# Older sqlalchemy-singlestoredb builds ship a VECTOR.result_processor that reads49# self._str_impl — an attribute only SQLAlchemy's JSON type defines, while VECTOR subclasses50# BLOB. Reading a VECTOR column through SQLAlchemy therefore raises AttributeError. Current51# builds set it in __init__; this fills it in when they have not, and is a no-op when they have.52try:53    from sqlalchemy import String as _SAString54    from sqlalchemy_singlestoredb.dtypes import VECTOR as _SAVector55
56    if not hasattr(_SAVector, '_str_impl'):57        _SAVector._str_impl = _SAString()58        print('applied the VECTOR._str_impl compatibility shim')59except ImportError:60    pass   # not using the SingleStore SQLAlchemy dialect61
62# Describing `embeddings` by hand stops LangChain running SELECT * on it to collect sample63# rows, which is what actually triggered the bug above, and keeps two 1536-dimension vectors64# out of the prompt. The three data tables still get real samples, which is the part that65# helps the agent write good SQL.66EMBEDDINGS_TABLE_INFO = """67CREATE TABLE embeddings (68    id BIGINT,                            -- auto increment69    category VARCHAR(255),                -- 'chatbot' for rows this notebook writes70    question LONGTEXT,71    question_embedding VECTOR(1536, F32), -- never SELECT this column; compare it instead72    answer LONGTEXT,73    answer_embedding VECTOR(1536, F32),   -- never SELECT this column; compare it instead74    created_at DATETIME75)76/* Semantic cache. Compare two vectors with DOT_PRODUCT(a, b), which returns a float. */77"""78
79db = SQLDatabase.from_uri(80    current_connection_url(),   # read now, not the possibly-expired startup copy81    include_tables=['embeddings', 'companyInfo', 'newsSentiment', 'stockTable'],82    sample_rows_in_table_info=2,83    custom_table_info={'embeddings': EMBEDDINGS_TABLE_INFO},84)85
86# Reuse the http_client from step 3 so the agent's calls also skip brotli encoding.87llm = ChatOpenAI(model=CHAT_MODEL, temperature=0, http_client=http_client)88
89agent_executor = create_sql_agent(90    llm=llm,91    toolkit=SQLDatabaseToolkit(db=db, llm=llm),92    agent_type='tool-calling',93    prefix=SQL_AGENT_PREFIX,94    top_k=3,95    max_iterations=5,96    verbose=True,97)98
99
100def run_agent(question: str) -> str:101    """Ask the SQL agent a question and return just its answer text."""102    return agent_executor.invoke({'input': question})['output']103
104
105print(f'agent ready over tables: {db.get_usable_table_names()}')
This is the idea the demo is built around. An agent run costs several seconds and a few thousand tokens,
and many questions users ask are questions somebody already asked, worded differently. So before paying
for a run: embed the question, look for a stored one pointing in nearly the same direction, and if it
scores above a threshold, return its stored answer. Because the vectors live in the same database as the
data, that lookup is a single DOT_PRODUCT query over a VECTOR column.
process_user_question() below is the whole mechanism, and it prints which path it took.
The similarity threshold is a property of the embedding model. 0.85 is right for
text-embedding-3-small; a number borrowed from a different model can mean the cache silently never
hits and you pay for every answer. The next cell measures it rather than trusting it.
In [17]:
1table_name = 'embeddings'2# Recalibrated for text-embedding-3-small. 0.97 was carried over from text-embedding-ada-002,3# whose cosine scores sit in a narrow band near the top of the range — unrelated text scored4# ~0.7 there, so 0.97 was a reasonable "nearly the same". The 3-small model spreads scores much5# wider, so the same number now means "almost character-for-character identical" and the cache6# never hits. The calibration cell below measures where paraphrases actually land.7similarity_threshold = 0.858
9
10def to_hex(vector: list[float]) -> str:11    """Pack an embedding as the little-endian float32 bytes a VECTOR(1536, F32) expects."""12    return np.array(vector, dtype='<f4').tobytes().hex()13
14
15def process_user_question(question: str, category: str = 'chatbot') -> str:16    print(f'\nQuestion asked: {question}')17
18    start = time.time()19    question_embedding = get_embeddings([question])[0]20    print(f'  embedding the question: {(time.time() - start) * 1000:.0f} ms')21
22    lookup = f"""23        SELECT question, answer,24               DOT_PRODUCT(question_embedding, UNHEX(%(qhex)s)) :> float AS score25        FROM {table_name}26        WHERE category = %(category)s27        ORDER BY score DESC28        LIMIT 129    """30
31    with s2_conn.cursor() as cur:32        start = time.time()33        cur.execute(lookup, {'qhex': to_hex(question_embedding), 'category': category})34        row = cur.fetchone()35        print(f'  cache lookup: {(time.time() - start) * 1000:.0f} ms')36
37    if row is not None:38        cached_question, cached_answer, score = row39        print(f'  closest stored question: "{cached_question}" (score {score:.4f})')40
41        if score > similarity_threshold:42            print('  -> cache hit, returning the stored answer')43            return cached_answer44    else:45        print('  cache is empty')46
47    print('  -> cache miss, running the agent')48    start = time.time()49    answer = run_agent(question)50    print(f'  agent run: {(time.time() - start) * 1000:.0f} ms')51
52    answer_embedding = get_embeddings([answer])[0]53
54    insert = f"""55        INSERT INTO {table_name}56            (category, question, question_embedding, answer, answer_embedding, created_at)57        VALUES58            (%(category)s, %(question)s, UNHEX(%(qhex)s), %(answer)s, UNHEX(%(ahex)s),59             %(created_at)s)60    """61
62    with s2_conn.cursor() as cur:63        cur.execute(insert, {64            'category': category,65            'question': question,66            'qhex': to_hex(question_embedding),67            'answer': answer,68            'ahex': to_hex(answer_embedding),69            'created_at': datetime.now().strftime('%Y-%m-%d %H:%M:%S'),70        })71
72    return answer
A semantic cache has one tuning knob and two ways to get it wrong. Too high and it never hits. Too low and it returns a stored answer to a question that merely sounds similar — which is worse, because a wrong answer arrives looking exactly like a right one.
So this cell scores a few pairs whose relationship you already know: an identical question, two
rewordings, an unrelated question, and one pair that matters more than the rest. It costs a single
embeddings request. Read the gap between the paraphrases and the unrelated pair — your threshold
belongs inside it. With text-embedding-3-small the rewordings land close to 0.9 and the unrelated
pair well below, which is why 0.85 sits where it does. Trust the numbers the cell prints over any
number written in prose, including these.
The first line of output is a check rather than a result: DOT_PRODUCT equals cosine similarity only
for unit-length vectors, so those norms should print as 1.0.
Watch the last row. Bullish and bearish score close together, because an embedding captures what a sentence is about more strongly than which way round it points — the honest limit of caching on similarity alone.
In [18]:
1# Which similarity a paraphrase actually scores is a property of the embedding model, so this2# measures it rather than trusting a threshold inherited from a different one. Costs one3# embeddings request, and nothing from the Alpha Vantage quota.4CALIBRATION_PAIRS = [5    ('identical but for a stopword', 'describe the database', 'describe database'),6    ('same question, reworded',      'describe the database', 'what tables are in here?'),7    ('same intent, longer',          "what is TSLA's average closing price?",8                                     'give me the mean close for TSLA'),9    ('unrelated',                    'describe the database',10                                     'which tickers have the most bullish news?'),11    ('OPPOSITE meaning',             'which tickers have the most bullish news?',12                                     'which tickers have the most bearish news?'),13]14
15texts = sorted({text for _, left, right in CALIBRATION_PAIRS for text in (left, right)})16vectors = dict(zip(texts, get_embeddings(texts)))17
18# DOT_PRODUCT equals cosine similarity only for unit-length vectors. OpenAI's embeddings are19# normalised, which is what lets the SQL lookup use the cheaper DOT_PRODUCT — worth confirming20# rather than assuming, since the scores below would mean something else if it were not true.21norms = [float(np.linalg.norm(v)) for v in vectors.values()]22print(f'vector norms: {min(norms):.4f} to {max(norms):.4f} '23      f'(1.0 means DOT_PRODUCT is cosine similarity)\n')24
25print(f'{"relationship":<30} score   hit at {similarity_threshold}?')26
27for label, left, right in CALIBRATION_PAIRS:28    score = float(np.dot(vectors[left], vectors[right]))29    print(f'{label:<30} {score:.4f}  {"YES" if score > similarity_threshold else "no"}')30
31print(f'\nsimilarity_threshold is {similarity_threshold}. It wants to sit above the unrelated '32      f'pair and below the rewordings;\nif your numbers differ from the commentary above, trust '33      f'these and adjust it.')
Two questions that mean the same thing, worded differently. The first is a miss: it prints the agent's
whole chain of thought — Entering new SQL Agent Executor chain, the queries it writes, the rows it
gets back — and takes around 8 seconds. The second scores above the threshold and comes straight back
from SingleStore in under a second, nearly all of which is the round trip to embed the question. The
absence of that agent chain on the second question is the entire point: that is the latency, the
tokens and the money saved.
The cell clears the cache first so the demonstration still works on a re-run — otherwise both
questions hit and there is nothing to compare. The SELECT after it shows what got stored.
In [19]:
1question_1 = 'describe the database'2question_2 = 'describe database'3
4# Start from an empty cache, or the demo stops demonstrating anything: on a second run the5# stored copy of question_2 would match itself at 1.0 and "hit" for the wrong reason. Only the6# chatbot rows go — anything else in the table is left alone.7with s2_conn.cursor() as cur:8    cur.execute("DELETE FROM embeddings WHERE category = 'chatbot'")9
10answer = process_user_question(question_1)11print(f'\nThe answer is: {answer}')
In [20]:
1%%sql2SELECT id, category, question, LEFT(answer, 120) AS answer_start FROM embeddings
Now the second question — the same request worded differently. Expect a cache hit with its score, no agent chain, and a total well under a second.
In [21]:
1answer = process_user_question(question_2)2print(f'\nThe answer is: {answer}')
The agent's answer is text. This step turns it into speech, plays it, and transcribes it back — the
"speak" and "hear" of the title. This cell only defines helpers, so expect no output. speak(text)
writes an mp3 and returns its path, preferring ElevenLabs when you supplied a key and using OpenAI's
gpt-4o-mini-tts otherwise, printing which engine and voice produced the file. kernel_value(name)
looks up a notebook variable and returns None if the cell that sets it has not run, so re-running
step 5 on its own after a kernel restart gives you a message naming the cell to run rather than a bare
NameError.
Any answer about your ElevenLabs account — no key, a free plan refusing a library voice, a spent quota — prints what happened and continues with OpenAI's voice. A real error still stops the cell, so the transcription step always has a file to read.
In [22]:
1from IPython.display import Audio, display2
3
4def kernel_value(name: str):5    """A notebook-level value, or None if the cell that sets it has not run.6
7    Step 5 is the section people re-run on its own — after a kernel restart, or to try a8    different voice — and a restart keeps no variables. Looking the keys up this way lets the9    helpers below say which cell to go back and run, instead of raising a bare NameError from10    somewhere inside themselves.11    """12    return globals().get(name)13
14# Free ElevenLabs plans cannot use *library* voices over the API: the request comes back 40215# with "Free users cannot use library voices via the API". Which voices count as library ones16# has changed over time — the long-familiar "Rachel" ID is one of them now — so rather than17# hard-coding an ID, ask the account what it has and pick something that will work.18ELEVENLABS_VOICE_ID = None   # filled in below; set it by hand to override the choice19
20
21def elevenlabs_voices() -> list:22    """The voices this key can see, the ones a free plan can actually use first."""23    key = kernel_value('elevenlabs_apikey')24
25    if not key:26        return []27
28    response = requests.get(29        'https://api.elevenlabs.io/v1/voices',30        headers={'xi-api-key': key},31        timeout=30,32    )33    response.raise_for_status()34
35    # 'premade' voices ship with every account and synthesize on the free plan. Anything the36    # account added from the voice library is paid-only over the API, so sort those last37    # instead of dropping them — they are the right choice on a paid key.38    return sorted(response.json()['voices'],39                  key=lambda voice: voice.get('category') != 'premade')40
41
42def elevenlabs_speak(text: str, voice_id: str) -> bytes:43    """mp3 bytes from ElevenLabs, or None if the plan or key will not allow it."""44    response = requests.post(45        f'https://api.elevenlabs.io/v1/text-to-speech/{voice_id}',46        headers={47            'Accept': 'audio/mpeg',48            'Content-Type': 'application/json',49            'xi-api-key': kernel_value('elevenlabs_apikey'),50        },51        json={52            'text': text,53            'model_id': 'eleven_multilingual_v2',54            'voice_settings': {'stability': 0.5, 'similarity_boost': 0.5},55        },56        timeout=120,57    )58
59    if response.ok:60        return response.content61
62    # ElevenLabs reports plan, key and quota problems as JSON with a 4xx, not as audio. A63    # plan limit is not a broken notebook, so report it and let the caller use OpenAI; a64    # genuine error — bad request, unknown voice, service down — should still stop the cell.65    # The refusal is usually {"detail": {"status": ..., "message": ...}}, but a bare string66    # and an html error page both turn up, so anything else counts as no detail at all.67    detail, code = {}, ''68
69    if 'json' in response.headers.get('Content-Type', ''):70        body = response.json()71
72        if isinstance(body, dict) and isinstance(body.get('detail'), dict):73            detail = body['detail']74            code = detail.get('status') or detail.get('code') or ''75
76    if response.status_code in (401, 402, 429) or code in (77            'payment_required', 'paid_plan_required', 'quota_exceeded'):78        print(f'ElevenLabs declined ({response.status_code} {code or "error"}): '79              f'{detail.get("message", response.text[:200])}')80        print('  Falling back to OpenAI text-to-speech. Nothing else in the notebook changes.')81        return None82
83    raise RuntimeError(f'ElevenLabs returned {response.status_code}: {response.text[:400]}')84
85
86def openai_speak(text: str) -> bytes:87    """mp3 bytes from OpenAI, the fallback that needs no third account."""88    openai_client = kernel_value('client')89
90    if openai_client is None:91        raise RuntimeError(92            'No OpenAI client in this kernel. Re-run the "Set API keys" cell and the cell that '93            'builds `client` in step 2 — a restarted kernel keeps none of its variables.')94
95    return openai_client.audio.speech.create(96        model='gpt-4o-mini-tts',97        voice='alloy',98        input=text,99        response_format='mp3',100    ).read()101
102
103def speak(text: str, path: str = 'output.mp3') -> str:104    """Synthesize `text` to an mp3 at `path`. Uses ElevenLabs if it can, else OpenAI."""105    audio_bytes, engine = None, 'OpenAI gpt-4o-mini-tts'106
107    if kernel_value('elevenlabs_apikey'):108        voice_id = ELEVENLABS_VOICE_ID or (elevenlabs_voices() or [{}])[0].get('voice_id')109
110        if voice_id:111            audio_bytes = elevenlabs_speak(text, voice_id)112            if audio_bytes:113                engine = f'ElevenLabs eleven_multilingual_v2, voice {voice_id}'114
115    if audio_bytes is None:116        audio_bytes = openai_speak(text)117
118    with open(path, 'wb') as f:119        f.write(audio_bytes)120
121    print(f'{engine} wrote {len(audio_bytes):,} bytes to {path}')122    return path
GET /v1/voices lists the voices your key can see, with each one's category. Only premade voices
synthesize on the free plan — a voice added from the voice library is paid-only over the API even though
it plays fine in the ElevenLabs web app, and the refusal comes when you synthesize, not when you list.
So this cell sorts the premade voices first, sets ELEVENLABS_VOICE_ID to one of them, and labels each
row with whether the free plan can use it — assign the variable yourself to override. If you skipped the
ElevenLabs key, it prints the OpenAI voices that will be used instead.
In [23]:
1voices = elevenlabs_voices()2
3for voice in voices[:8]:4    category = voice.get('category', 'unknown')5    usable = 'free plan OK' if category == 'premade' else 'paid plan only over the API'6    print(f"  {voice['voice_id']}  {voice['name']:<12} {category:<10} ({usable})")7
8if voices:9    # First entry is a premade voice when the account has one, because of the sort above.10    ELEVENLABS_VOICE_ID = voices[0]['voice_id']11    print(f"\nUsing {voices[0]['name']} ({ELEVENLABS_VOICE_ID}).")12
13    if voices[0].get('category') != 'premade':14        print('  No premade voice on this account, so this one may return 402 — '15              'speak() will fall back to OpenAI if it does.')16elif kernel_value('elevenlabs_apikey') is None:17    print('The "Set API keys" cell has not run in this kernel, so there is no key to list.')18    print('Re-run it if you want ElevenLabs; everything below works on OpenAI without it.')19else:20    print('No ElevenLabs key — using OpenAI text-to-speech.')21    print('OpenAI voices: alloy, echo, shimmer, coral, sage, ash, ballad, verse')
Now speak the answer the agent produced in step 4, and play it back. Expect a line naming the
engine and voice, the number of bytes written, and an audio player that starts on its own. The
file is output.mp3 in the notebook's working directory.
In [24]:
1audio_path = speak(answer)2display(Audio(filename=audio_path, autoplay=True))
Reading the audio back with whisper-1 is the "hear" half. Expect a transcript that closely matches
the spoken answer — punctuation and capitalisation will differ, and numbers may come back as words,
which is a fair illustration of what transcription does and does not preserve. In a real application
the input would be a user speaking; round-tripping here means the notebook has an audio file to work
with without asking you for a microphone.
In [25]:
1with open(audio_path, 'rb') as audio_file:2    transcript = client.audio.transcriptions.create(model='whisper-1', file=audio_file)3
4print(transcript.text)
The last modality. newsSentiment stores each article's banner photo URL next to its headline,
sentiment scores and publication time, so the image and the structured data describing it are in the
same row — and captioning the photo can be grounded in the columns beside it. Three cells: ask the
agent for a recent article, fetch that article's photo, caption it with a vision model. Then one more
to speak the caption using step 5's speak().
No new dependency and no new account: the vision model is the same OpenAI client from step 2, and captioning is one extra content part in an ordinary chat request.
A third question for the agent, asking for the most recent Amazon article above a relevance threshold,
with its URL and banner image. Expect an agent run — a cache miss, since the question is new — and an
answer quoting the article. The %%sql cell after it shows the same articles the agent was looking at.
The next cell takes its URL from that table rather than from the agent's prose: for fetching bytes you
want the exact string that was stored, not a model's transcription of it.
In [26]:
1question_3 = (2    'What is the most recent news article for Amazon where the topic_relevance_score is '3    'greater than 90%? Include the url, time published and banner image.'4)5
6answer = process_user_question(question_3)7print(f'\nThe answer is: {answer}')
In [27]:
1%%sql2SELECT title, url, time_published, banner_image3FROM newsSentiment4WHERE ticker = 'AMZN' AND topic_relevance_score > 0.95ORDER BY time_published DESC6LIMIT 3
This is the one cell that may need a settings change. A hosted notebook reaches the internet through
the workspace firewall, which allows a named list of hosts. Alpha Vantage and OpenAI are on it; news
publishers' image CDNs are not, and there is no single host to add, because one article's banner sits on
s.yimg.com while the next is on www.marketbeat.com or cdn.benzinga.com. So the cell tries one fetch
per distinct CDN across the most recent articles, keeping the first image that arrives. Expect either a
photo rendered inline, or a short report per host.
If every host is blocked, the cell prints the hostnames it tried — those are exactly what to allow, on a
Cannot access <host> toast in the portal or in the workspace group's firewall settings, which take
wildcards such as *.yimg.com. Nothing above this point touches those hosts, so leaving the firewall
alone costs you step 6 only.
The cell fetches the bytes in the kernel rather than pointing the browser or OpenAI at the remote URL, for the reason the next cell explains.
In [28]:
1import base642from urllib.parse import urlparse3
4from IPython.display import HTML, display5
6# Take the URLs from the table rather than the model's prose, so they are exactly what we7# stored. Several candidates, not one: banner images are hosted on whatever CDN the publisher8# uses, and this kernel can only reach the hosts its firewall allows (see below).9with s2_conn.cursor() as cur:10    cur.execute("""11        SELECT title, url, time_published, banner_image12        FROM newsSentiment13        WHERE ticker = 'AMZN'14          AND topic_relevance_score > 0.915          AND banner_image != ''16          AND banner_image != 'None'17        ORDER BY time_published DESC18        LIMIT 2519    """)20    candidates = cur.fetchall()21
22assert candidates, (23    'No AMZN article with a banner image and topic_relevance_score > 0.9. Loosen the filter, '24    'or check that the news ingest above actually inserted rows.'25)26
27MAX_HOSTS = 6   # distinct image hosts to try before giving up, ~5s each when blocked28
29def image_mime(data: bytes, header: str = '') -> str:30    """The image's type, from the response header when it sent one, else from the magic bytes."""31    if header.startswith('image/'):32        return header.split(';')[0].strip()33
34    for prefix, mime in [(b'\xff\xd8\xff', 'image/jpeg'), (b'\x89PNG\r\n\x1a\n', 'image/png'),35                         (b'GIF87a', 'image/gif'), (b'GIF89a', 'image/gif')]:36        if data.startswith(prefix):37            return mime38
39    if data[:4] == b'RIFF' and data[8:12] == b'WEBP':40        return 'image/webp'41
42    return ''43
44
45# Fetch the bytes here in the kernel, then use those bytes everywhere below. It costs one46# request and removes two points of failure: your browser has to reach the news CDN to render a47# remote <img>, and OpenAI's servers have to reach it to caption one from a URL. The symptoms of48# either are unhelpful — a broken image, or a captioning call that simply hangs.49def fetch_image(url: str) -> tuple:50    """The image bytes and mime type, or (None, '') having said what went wrong.51
52    A host that is merely unhappy answers with a status code; one that is blocked does not53    answer at all and raises instead. Both happen with news banner images, so both are handled.54    """55    try:56        # Separate connect and read timeouts. A firewall-blocked host fails at connect, and57        # waiting 30 seconds for each of those is most of a coffee break for no information.58        response = requests.get(url, timeout=(5, 30))59    except requests.RequestException as exc:60        print(f'    unreachable: {type(exc).__name__}')61        return None, ''62
63    if not response.ok:64        print(f'    HTTP {response.status_code}')65        return None, ''66
67    mime = image_mime(response.content, response.headers.get('Content-Type', ''))68
69    if not mime:70        # Usually an error page served with a 200 status, which would otherwise be embedded71        # as a data URL of some html and captioned as if it were a photograph.72        print(f'    {len(response.content):,} bytes, but not a recognisable image')73        return None, ''74
75    print(f'    {len(response.content):,} bytes, {mime}')76    return response.content, mime77
78
79# This kernel reaches the internet through the workspace firewall, which allows a specific list80# of hosts. Alpha Vantage and OpenAI are on it because the notebook needs them; publishers'81# image CDNs are not, and which CDN a banner uses depends on the article. So try the candidates82# in turn, one attempt per distinct host, and keep the first image that actually arrives.83title = article_url = published = banner_image_url = None84banner_image_bytes, banner_image_mime, banner_image_data_url = None, '', None85tried = []86
87for candidate in candidates:88    candidate_title, _, candidate_published, candidate_banner = candidate89    host = urlparse(candidate_banner).hostname or ''90
91    if not host or host in tried:92        continue93
94    tried.append(host)95    print(f'{host}  ({candidate_published}  {candidate_title[:60]})')96    data, mime = fetch_image(candidate_banner)97
98    if data:99        title, article_url, published, banner_image_url = candidate100        banner_image_bytes, banner_image_mime = data, mime101        break102
103    if len(tried) >= MAX_HOSTS:104        break105
106if banner_image_bytes:107    # A data: URL renders with no network access at all, and works for webp, which the news108    # wires use heavily and IPython.display.Image will not inline.109    banner_image_data_url = (110        f'data:{banner_image_mime};base64,'111        + base64.b64encode(banner_image_bytes).decode('ascii')112    )113    print(f'\nCaptioning the banner from: {title}')114    display(HTML(f'<img src="{banner_image_data_url}" alt="{title}" '115                 f'style="max-width: 100%; height: auto">'))116else:117    print(f'\nNone of those {len(tried)} hosts returned an image. That is the workspace '118          'firewall: the kernel can only reach hosts it allows, and image CDNs are not on the '119          'list. Allow any one of these and re-run this cell:')120
121    for host in tried:122        print(f'    {host}')123
124    print('The portal raises a "Cannot access <host>" toast for each of them; the ones naming a '125          'domain have an "Add to Firewall" link that does it in one click. (Toasts showing a '126          'bare IP address are the same requests seen lower down and have no link — the domain '127          'is what the rule needs.) A wildcard like *.yimg.com works in the workspace group\'s '128          'firewall settings if you would rather not add each subdomain.')129    print('Step 6 is the only part of the notebook that needs these hosts, so everything above '130          'keeps working either way.')
Expect one or two sentences describing the photo, in the style of alt text, after a few seconds.
The image goes to the model in the same message as the instruction, as the base64 data: URL the
previous cell built. Sending the news site's own link instead would make OpenAI's servers fetch it,
which fails as a long hang followed by an error about a URL you can open yourself.
The article's headline is passed as context alongside the image. That is the point the step is making: the caption is grounded in a structured column from the very same row as the photo.
In [29]:
1assert banner_image_data_url, (2    'No image bytes to caption — the cell above could not fetch a banner from any of the hosts '3    'it tried. Allow one of the hostnames it listed in the workspace firewall and re-run it. '4    'Captioning deliberately does not fall back to the remote URL: that would make OpenAI fetch '5    'the CDN instead, which usually ends in a long hang rather than a clear message.'6)7
8response = client.chat.completions.create(9    model=CHAT_MODEL,10    messages=[{11        'role': 'user',12        'content': [13            {14                'type': 'text',15                'text': (16                    'Caption this image from a news article in one or two sentences, '17                    'as you would for a screen reader. Describe only what is visible. '18                    f'For context, the article headline is: "{title}"'19                ),20            },21            # The data: URL from the cell above, so OpenAI captions the bytes we already22            # hold rather than trying to fetch the news CDN itself.23            {'type': 'image_url', 'image_url': {'url': banner_image_data_url}},24        ],25    }],26    max_completion_tokens=150,27)28
29caption = response.choices[0].message.content30print(caption)
Finally, speak the caption with the same speak() helper from step 5, writing caption.mp3 this
time so the answer's audio is still there to compare. All four modalities have now been through one
database: rows in, question in English, answer spoken, image seen and described.
In [30]:
1caption_path = speak(caption, path='caption.mp3')2display(Audio(filename=caption_path, autoplay=True))
The errors worth knowing about before you need them. The two marked lies about its cause are the reason this table exists.
| What you see | What it means | What to do |
| --- | --- | --- |
| NameError or ModuleNotFoundError | The cell that defines it has not run in this kernel; a restart keeps no variables | Re-run step 2 from the top |
| OperationalError: 2628: JWT token expired | The connection URL's password is a JWT that lasts about an hour | Restart the kernel, which gets a fresh token |
| no database is selected, or missing tables | The drop-down at the top points somewhere other than llm_webinar | Select the database, re-run step 1, then the connect cell |
| Lies about its cause: APIConnectionError under a successful HTTP/1.1 200 OK | Not the network and not your key — a brotli decoder failed after the response arrived | Re-run the OpenAI client cell in step 2, which turns brotli off |
| stopped early on the quota limit, or a pause and retry, in step 3 | The two Alpha Vantage limits: 25 per day, and about one per second | The per-second one retries itself. For the daily one, continue with partial data or re-run after the reset |
| Lies about its cause: the cache never hits, and nothing errors | The similarity threshold does not match the embedding model | Run the calibration cell in step 4 and use the measured gap |
| AttributeError: 'VECTOR' object has no attribute '_str_impl' | A SQLAlchemy-only bug in some builds of the SingleStore dialect | Re-run the agent cell in step 4, which patches it in |
| ElevenLabs declined (402 paid_plan_required) | Free plans can only synthesize premade voices | Nothing — it falls back to OpenAI |
| Cannot access <host> in step 6 | News image CDNs are not on the workspace firewall's allowlist | Add to Firewall on a toast naming a domain, then re-run that cell |
One database, four modalities. Prices, company profiles and news went into SingleStore; a question asked in English came back answered; the answer was spoken and heard again as text; and a photo belonging to one of those rows was described in a sentence grounded in the row beside it.
None of it needed a second datastore. The cache lookup in step 4 is a SELECT with a DOT_PRODUCT
against the same tables the agent queries — no export, no sync job, and because the cache is just a
table, you can SELECT from it to see why it hit.
The cell below drops the llm_webinar database — tables, rows, cache and all. Nothing else in this
notebook destroys data, so it is the only cell to be careful with.
Refilling the tables costs about a dozen Alpha Vantage requests against an allowance of 25 per day. To start the demo over without touching the data, re-run the cache test in step 4 instead.
In [31]:
1%%sql2DROP DATABASE IF EXISTS llm_webinar;
Using OpenAI to build an app that can take images, audio, and text data to generate output
This Notebook can be run in Standard and Enterprise deployments.
Launch this notebook in SingleStore and start executing queries instantly.
This Notebook has been released under the Apache 2.0 open source license.